GPT-6 Astra on Felo OpenAPI: 1.05M Context and Agent Tools

Felo OpenAPI adds GPT-6 Astra with a 1.05M context window, 128K max output, and compatible Chat Completions, Responses, and Messages endpoints.
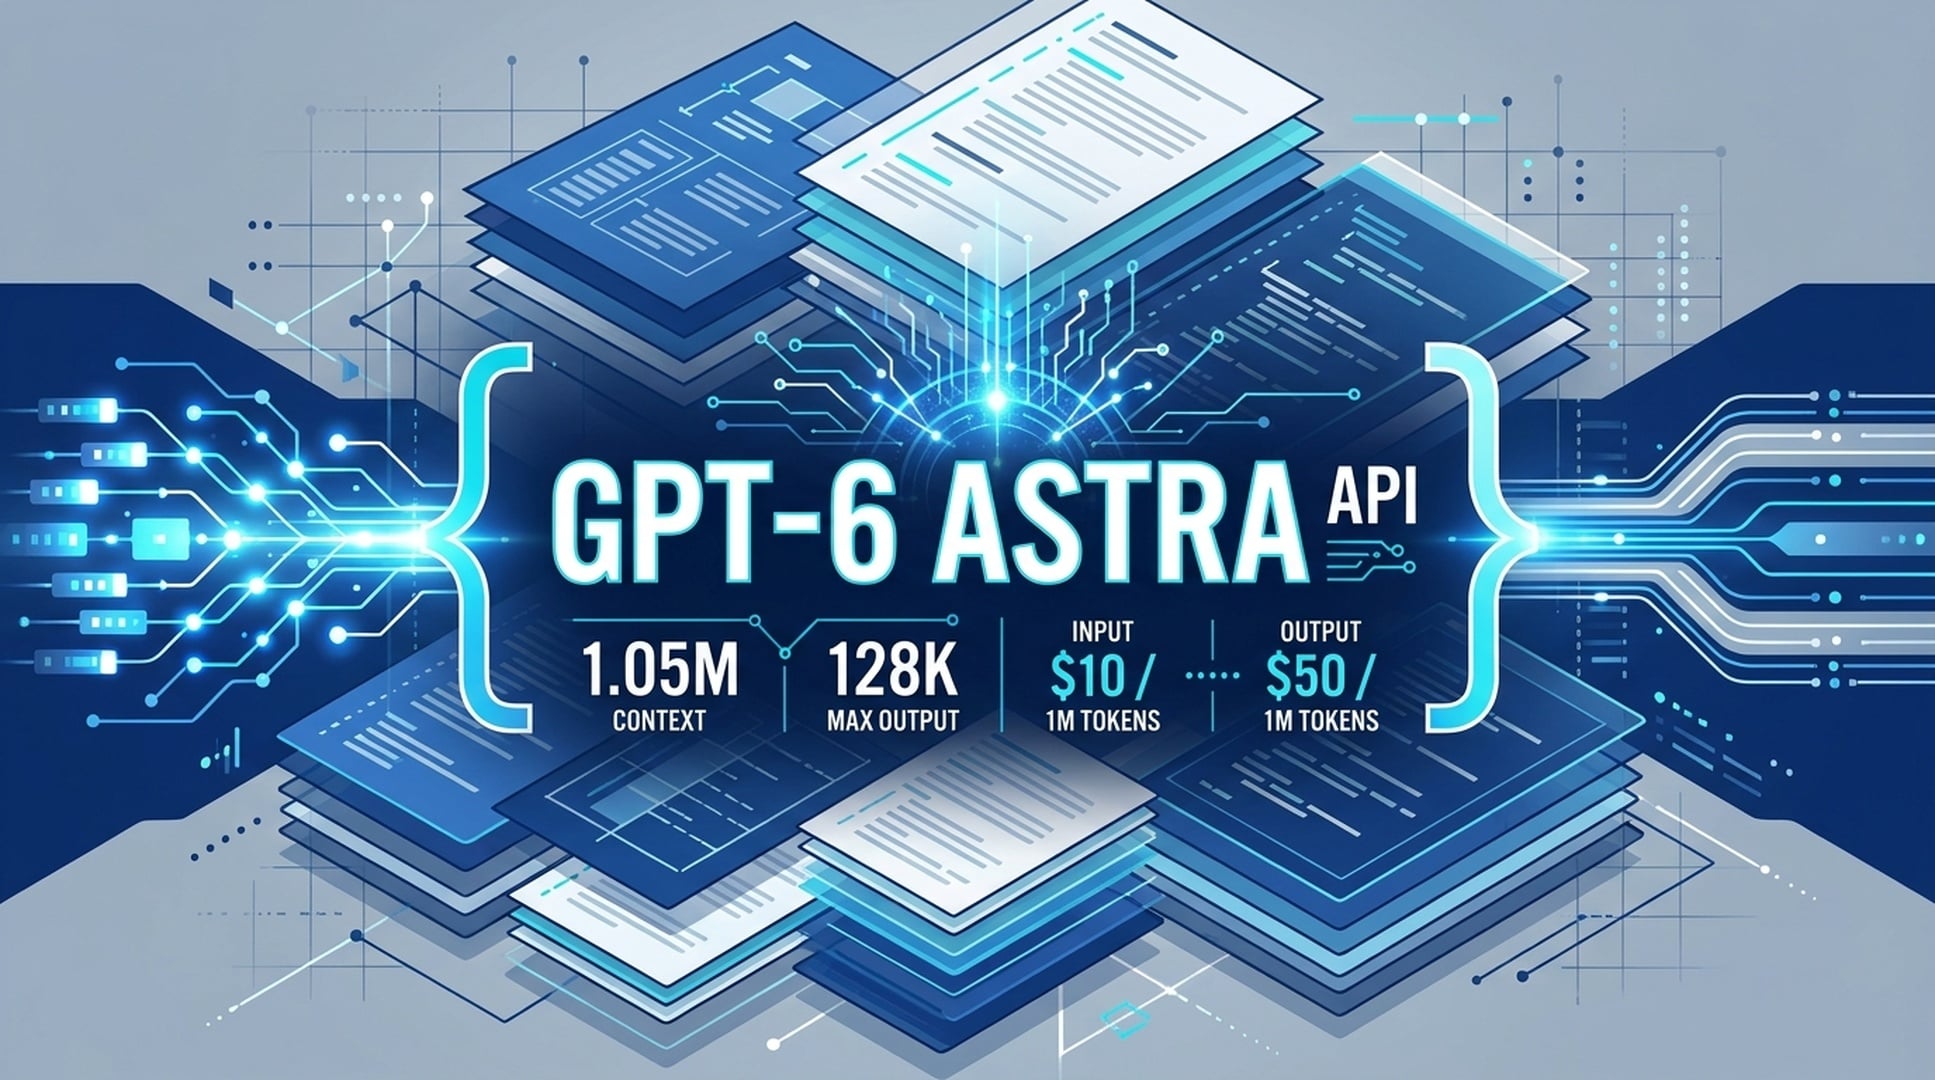
Long documents, complex code, and multi-step agent flows force teams to split model calls. Felo OpenAPI offers GPT-6 Astra, so one model ID can handle these workloads through compatible API surfaces.
Try GPT-6 Astra: https://openapi.felo.ai/models/openai/gpt-6-astra
What GPT-6 Astra is built for
GPT-6 Astra is the flagship GPT-6 tier on Felo API Platform. OpenAI describes it as its most capable model for complex reasoning, coding, computer use, research, and document creation. The Felo model page lists Reasoning, Tools, JSON, Streaming, and Vision as capabilities.
Use the model ID gpt-6-astra. The context window is 1,050,000 tokens and the maximum output is 128,000 tokens. OpenAI lists a knowledge cutoff of April 30, 2026. This capacity lets a request hold a specification, a codebase summary, tool definitions, and conversation history in one working context.
OpenAI lists five reasoning-effort settings: low, medium, high, xhigh, and max. Pick the setting that matches the quality target, latency budget, and request cost.
The OpenAI announcement says GPT-6 Astra is rolling out to enterprises in the Trusted Access Program, with Plus, Pro, Business, and Enterprise access coming in the following days. Felo OpenAPI provides a model route for developers who need API access through its platform.
Three protocols, one model ID
Felo API Platform exposes three compatible request surfaces:
- Chat Completions:
POST https://openapi.felo.ai/api/v1/chat/completions - Responses:
POST https://openapi.felo.ai/api/v1/responses - Messages:
POST https://openapi.felo.ai/api/v1/messages
An app with an OpenAI-compatible client can keep its request structure and change the model value to gpt-6-astra. Claude-style clients can use the Anthropic-compatible Messages surface. The model page lists Claude Code, Codex, LLM API, and other agent clients as use cases.
Pricing that belongs in the budget
The current Felo model page lists these rates:
| Item | Rate |
|---|---|
| Input | $10.00 per 1M tokens |
| Output | $50.00 per 1M tokens |
The page says launch pricing may be up to 50% lower than official provider API rates. Final cost depends on the model, input/output mix, cache use, and active plan. The current Felo page lists $10.00 / 1M input tokens and $50.00 / 1M output tokens. A cost estimate includes each variable; the headline rate is not the full bill.
OpenAI's model documentation lists standard rates of $10.00 per 1M input tokens, $1.00 per 1M cached input tokens, and $50.00 per 1M output tokens. Cache writes use 1.25x the uncached input rate. Requests above 272K input tokens use 2x input and cache rates plus 1.5x output for the full request. Batch and Flex use 50% of standard rates; Fast mode uses 2x the applicable rates. These are OpenAI reference rates, not a replacement for the Felo plan price above.
| Price source | Input | Cached input | Output |
|---|---|---|---|
| Felo model page | $10.00 / 1M | Page lists cached-input and cache-write rates | $50.00 / 1M |
| OpenAI model guide | $10.00 / 1M | $1.00 / 1M | $50.00 / 1M |
Make a first request in five steps
1. Create an API key
Create a key in your Felo API Platform account and set it as an environment variable:
export FELO_API_KEY="YOUR_API_KEY"
2. Set the endpoint
For Chat Completions, use:
https://openapi.felo.ai/api/v1/chat/completions
3. Set the model ID
Pass "model": "gpt-6-astra" with a messages array. This cURL request tests the route:
curl https://openapi.felo.ai/api/v1/chat/completions \
  -H "Authorization: Bearer $FELO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6-astra",
    "messages": [{"role": "user", "content": "Explain this API error."}]
  }'
4. Add tools or structured output
Compatible parameters include tools, tool_choice, and response_format. Support for each control depends on the selected protocol and model route. GPT-6 Astra supports reasoning; when the protocol and route expose reasoning controls, preserve returned reasoning metadata when continuing a conversation.
OpenAI lists these Responses API tools for GPT-6 Astra: web search, file search, image generation, code interpreter, hosted shell, apply patch, skills, computer use, MCP, and tool search. Use the Responses endpoint when a workflow needs these hosted tools. Felo's exposed surfaces and enabled tools can depend on the active route.
5. Turn on streaming
Set stream to true to receive server-sent events:
{
  "model": "gpt-6-astra",
  "stream": true,
  "messages": [{"role": "user", "content": "Summarize this log."}]
}
A preflight checklist
- Estimate input cost against the 1.05M context window.
- Set
max_tokensto keep output within the project budget. - Record input, output, cache, and plan data for each request estimate.
- Test prompts in the Playground before connecting an app or agent client.
- Keep regression samples for tools, JSON output, and streaming.
- Set
reasoning_effortto a supported level and record it with latency and cost data. - Use the OpenAI pricing rules for comparison; use the Felo plan and route for the payable estimate.
Start with the model page
GPT-6 Astra puts reasoning, coding, long-context analysis, and agent work behind one model entry. Felo OpenAPI gives teams a migration path through Chat Completions, Responses, and Messages. An existing client can stay in place while the request surface changes to match the workload.
Open the GPT-6 Astra model page for parameters, code samples, and the Playground entry.
Sources: Felo API Platform GPT-6 Astra model page, OpenAI GPT-6 Astra announcement, and OpenAI GPT-6 Astra model guide (accessed 2026-09-04). Felo pricing was checked again on 2026-09-04.